Ruang Topik: mapping Indonesian news topics
- Text Mining final project · Informatics Engineering, ITS · 2026
- Team project (3 people); all stages done together
- Python
- Gensim
- scikit-learn
- BERTopic
- UMAP
- HDBSCAN
- Optuna
- Sentence-Transformers
- Streamlit
The question
Thousands of news articles appear every day. Which topic-modeling method finds the clearest topics in Indonesian news, and what actually moves the quality of a neural topic model?
Data
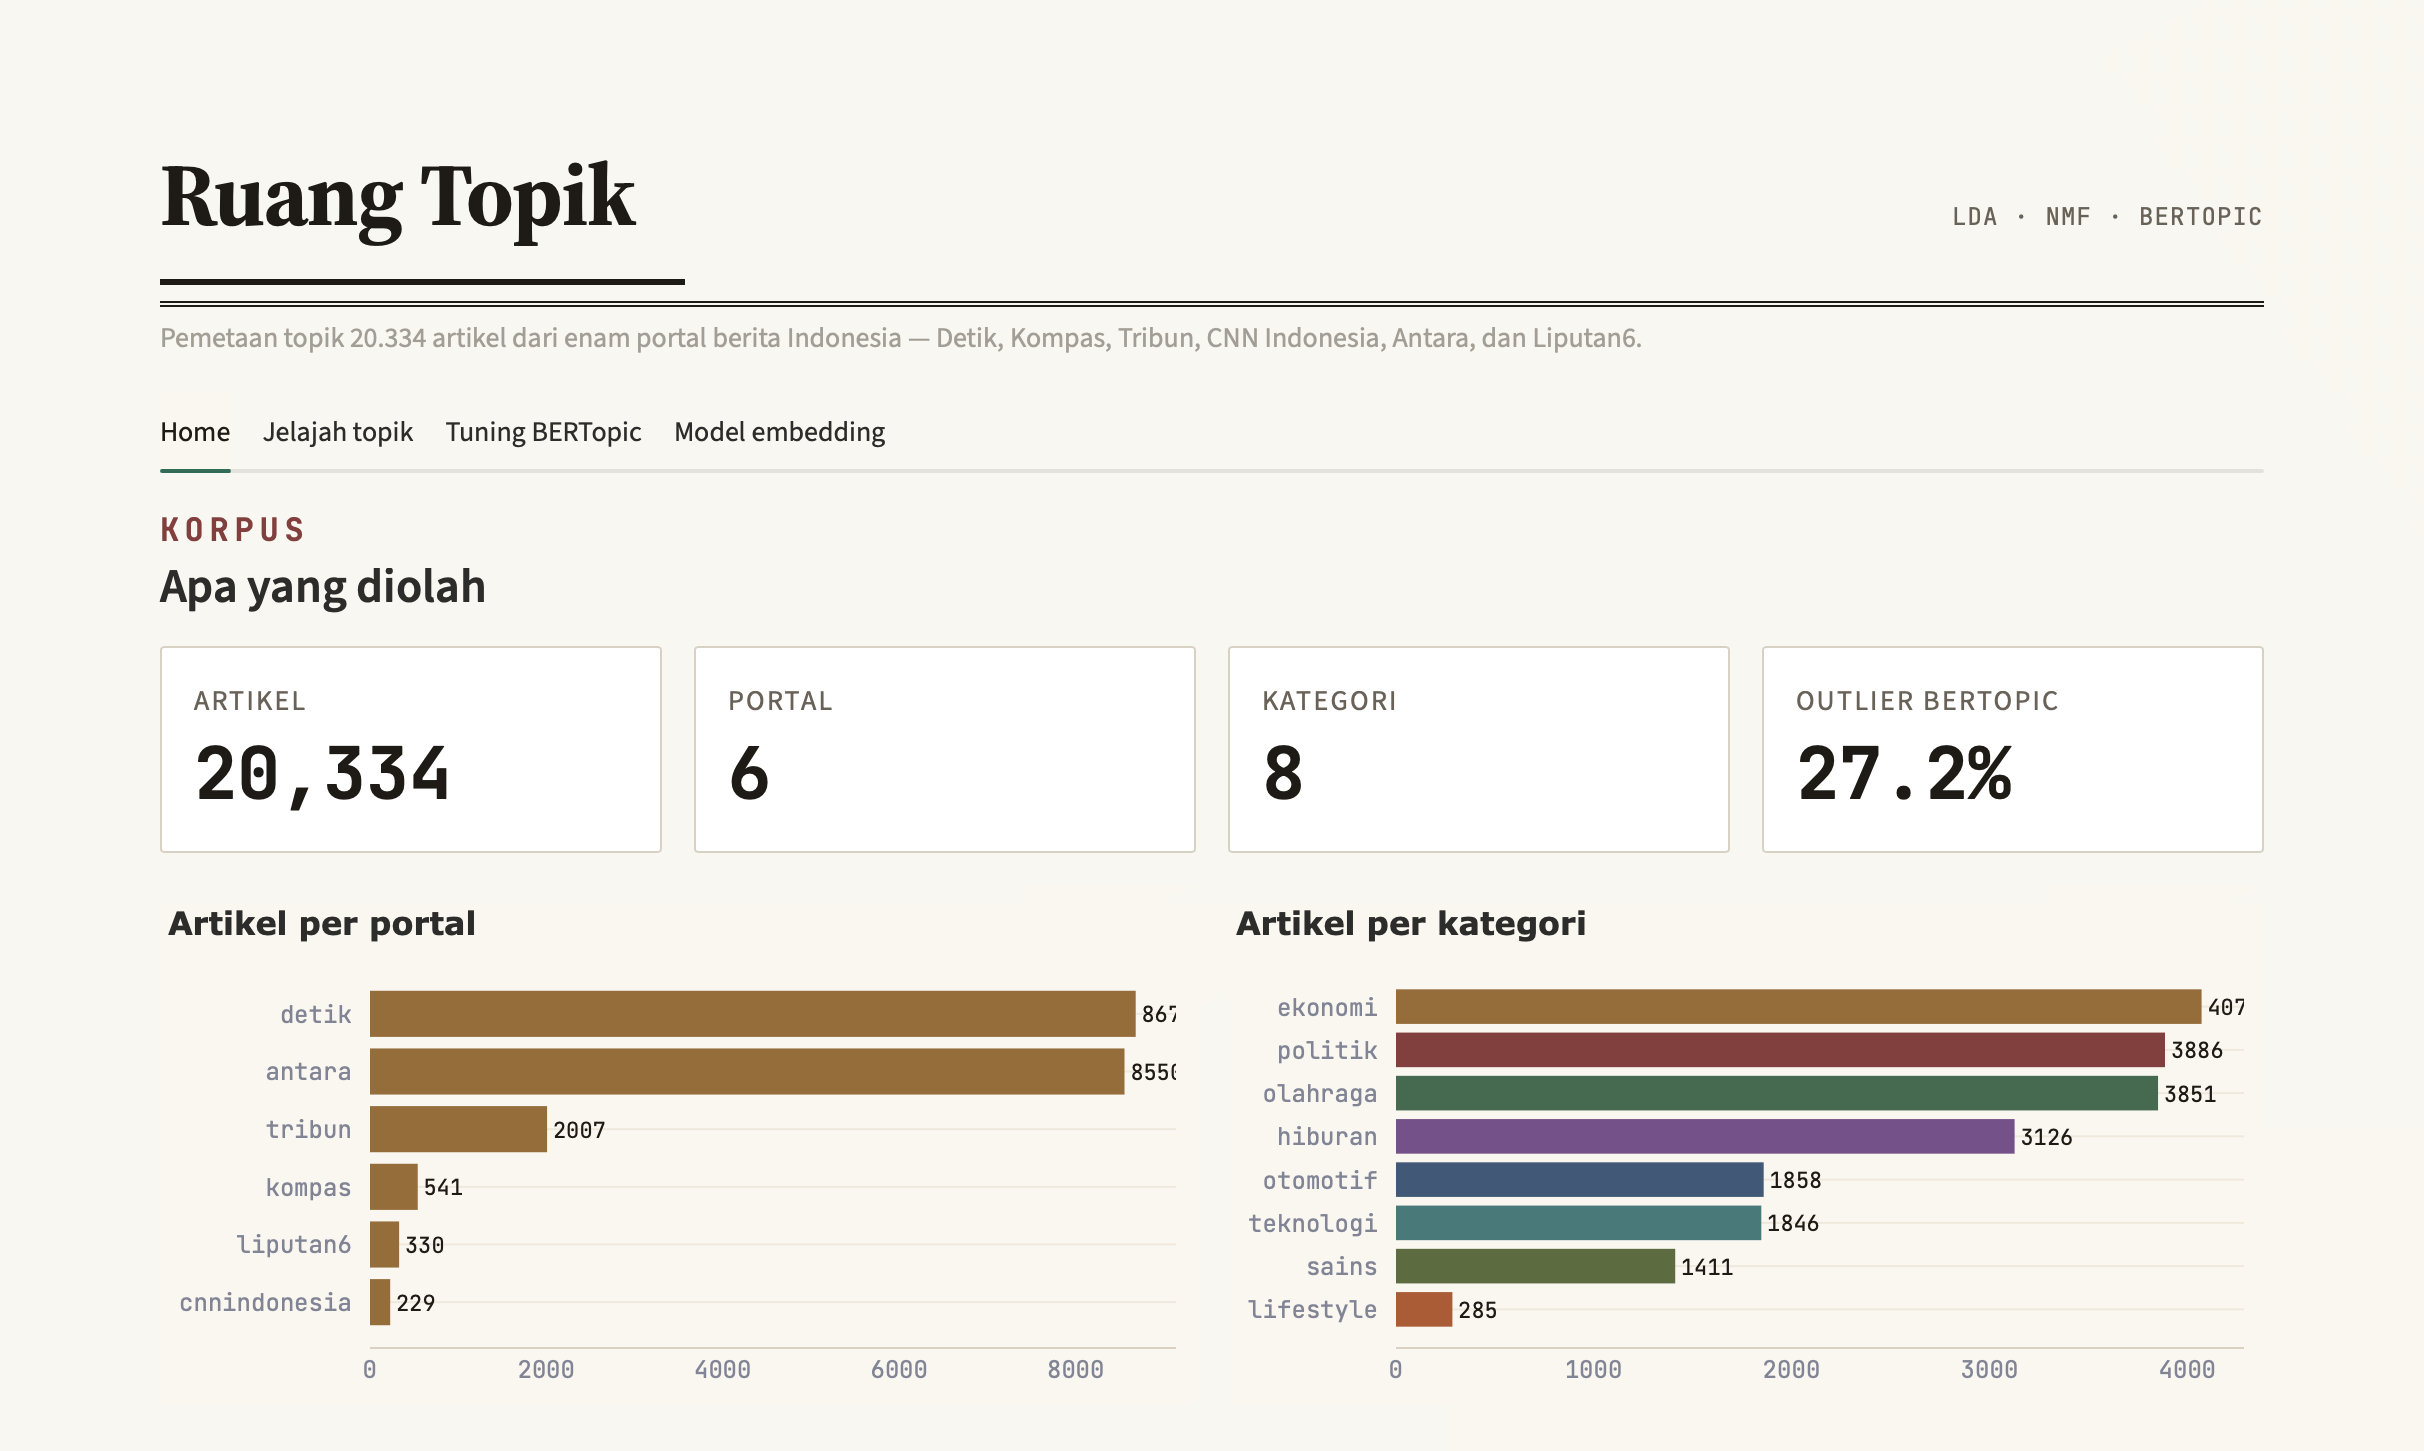
We scraped six national portals (Detik, Antara, Tribunnews, Kompas, Liputan6, CNN Indonesia): title, date, body, category, portal and URL. After preprocessing: 20,334 articles.
Three experiments
S1 · Which method? LDA and NMF for k ∈ {5…30}, BERTopic choosing k itself, all scored with C_v coherence on the same dictionary and reference corpus.
| Method | Approach | Topics | C_v |
|---|---|---|---|
| NMF | matrix factorisation | 25 | 0.825 |
| BERTopic | contextual embeddings | 19 (auto) | 0.778 |
| LDA | probabilistic | 25 | 0.616 |
NMF gave the sharpest topics (MotoGP, badminton, the rupiah exchange rate, macro-economy). BERTopic was more granular but left about 27% of documents as noise. LDA scored lowest but gives per-document topic probabilities, which multi-label classification needs.
S2 · Does tuning help BERTopic? 15 Optuna (TPE) trials over UMAP and HDBSCAN parameters.
Best C_v 0.799, a gain of +0.021. HDBSCAN min_cluster_size explained 81.8% of the effect.
Even the worst trial (0.758) beat the best LDA.
S3 · Does the embedding model matter? Five sentence-embedding models. A general multilingual model (paraphrase-multilingual-mpnet-base-v2, C_v 0.803) beat every Indonesian-specific model (0.728–0.789). The spread across embeddings (0.075) was about 3.5× the gain from tuning.
Takeaway
On this corpus, a classical method won on coherence, and for neural topic models the representation mattered far more than clustering hyperparameters. The mixed vocabulary of Indonesian news (loanwords, global names) likely favours multilingual models.